Bài 7 — Masking quyết định bài toán dự đoán#
Bắt đầu · Trước: training step · Tiếp: collapse và diagnostics
Mục tiêu và tiền đề#
Bạn sẽ đọc mask theo geometry, scale, context–target relation, adjacency, axis và schedule; tính một case cùng ratio nhưng khác thông tin. Cần token grid lớp 1, conditional prediction bài 2 và teacher contextualization bài 4. Trực giác: che xen kẽ chữ trong câu khác che toàn một từ; cùng số chữ bị che nhưng câu hỏi khác.
Notation: input grid có F frequency patches × T time patches. visible, target, dropped but not supervised nếu recipe có vùng ấy. Không mặc định là toàn grid hoặc mask ratio là loss coverage. Một recipe có thể có nhiều target blocks/masks.
1. Bốn thao tác “che” khác nhau#
| Thao tác | Student thật thấy gì? | Sequence/gradient implications |
|---|---|---|
| Patch removal | Chỉ visible token rows và original positions | Transformer sequence ngắn; masked content absent |
| Replace by mask embedding | Full-length sequence với learned/fixed mask values | Mask vị trí vẫn có attention rows; length giữ |
| Zero-input masking | Spectrogram/waveform giá trị zero tại vùng | Front-end vẫn xử lý vùng; zero có nghĩa phụ thuộc normalization/log floor |
| Downstream SpecAugment | Input classifier bị che; nhãn utterance vẫn như cũ | Regularization của supervised task, không tạo latent targets |
Patch removal sau projection không cùng zero trước projection: với bias b, ; zeros qua convolutions/attention/position embeddings không “không có gì”. Feature masking sau CNN cũng khác mask raw trước CNN do receptive field overlap. wav2vec2 §3.1, AudioMAE §3, Audio-JEPA code.
2. Lưới toy: 50% che chưa nói độ khó#
Đây là lưới giả lập 4 frequency rows × 8 time columns. C visible, M supervised target. Mỗi case 16/32 target positions; 16 context. Xét neighbors bốn hướng (up/down/left/right), không wrap biên, không diagonal.
Time → 1 2 3 4 5 6 7 8
A: checkerboard
f4     C M C M C M C M
f3     M C M C M C M C
f2     C M C M C M C M
f1     M C M C M C M C

B: middle time block
f4     C C M M M M C C
f3     C C M M M M C C
f2     C C M M M M C C
f1     C C M M M M C C

D: middle frequency band
f4     C C C C C C C C
f3     M M M M M M M M
f2     M M M M M M M M
f1     C C C C C C C C
Định nghĩa adjacency fraction
Case A: 16/16 targets có visible neighbor → A=1. Case B: chỉ target cols 3 và 6 sát visible cols 2/7; 8/16 → A=0,5. Case D: mỗi target row f2/f3 sát visible f1/f4 → A=1. Cùng ratio, A khác; cùng A, axis relation vẫn khác. Nearest-visible Manhattan distance ở B middle cols 4/5 là2, ở target edge cols là1; không diễn giải thành temporal seconds nếu chưa biết patch spans.
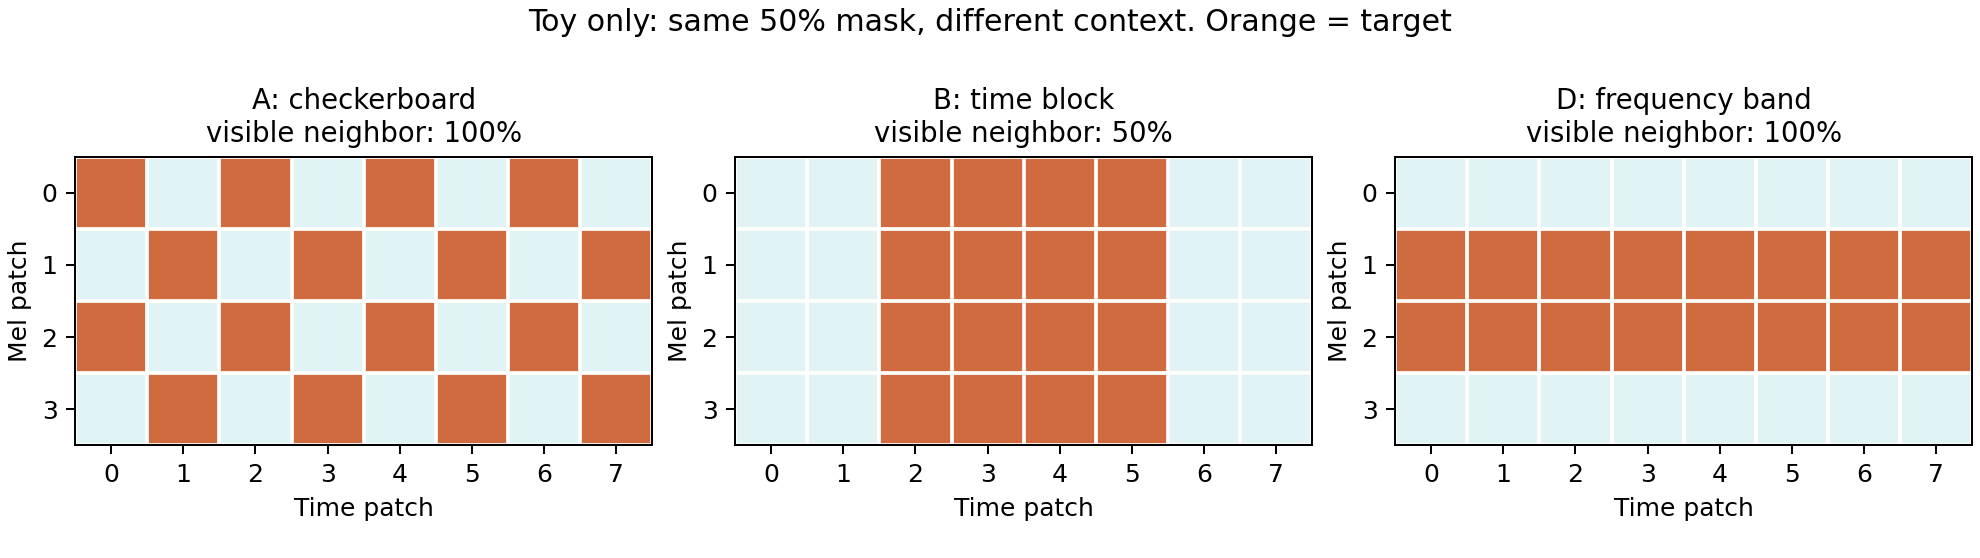
3. Geometry đổi predictability theo signal assumptions#
Toy signal , với cố định, là shared temporal trajectory, local residual. Giả sử a biết và nhỏ. Case A có nhiều local cues ở mỗi time. Case D còn visible frequency rows ở mọi t, cho biết s_t qua . Case B che toàn frequencies của t=3…6; context phải suy s_t trong khoảng bị thiếu bằng dynamics/structure xa hơn.
Đây là kết luận có điều kiện của toy, không theorem block mask luôn khó hơn với mọi speech. Nếu s_t periodic predictable, B vẫn dễ. Nếu bands f1/f4 không correlated với f2/f3, D có thể khó. Nếu artifact chính là unpredictable, mọi strategy có thể không cho dự đoán exact artifact draw. Full-input teacher latent cũng có thể bỏ hoặc contextualize residual khác raw target.
Ambiguity đã giải: context C cố định, hidden target U balanced ±1 independent C. Best MSE prediction 0, expected loss1. Nếu thêm một visible neighbor V=U, prediction V cho error0. Thay coverage/adjacency có thể đổi conditional variance ; nếu không có thêm information, tăng predictor capacity không xóa irreducible error. Ngược lại, high loss còn có thể do optimizer/predictor chưa học; chỉ error không phân biệt hai lý do.
4. Context–target overlap có nhiều nghĩa#
Raw overlap có thể tạo trivial copy path; nếu teacher target contextualized, copy không luôn exact nhưng task đã dễ theo cách khác. Context ở I-JEPA là sampled block lớn rồi loại các target regions; target blocks có thể overlap nhau. Không nhầm hai quan hệ. I-JEPA §3, Fig. 4 và Appendix A.1.
Audio-JEPA released random sampler lấy indices bằng permutation rồi split target/context; một target mask và complement context trong default recipe. Mẫu ratio/rounding khác geometry I-JEPA. RandomBlockMaskCollator, mask config.
Teacher nhìn full input gồm C và M là target contextualization, không cùng khái niệm student raw overlap C∩M. Teacher outputs selected at M có thể chứa C; điều đó là recipe đã nói, không mặc định leakage. Teacher output được compute từ test labels hoặc contaminated datasets mới là vấn đề khác cần protocol evidence.
Overlap của raw receptive fields/analysis windows lại là tầng khác: nonoverlapping patches trên log-mel có thể nhận STFT windows overlap về raw samples. Vì vậy “no token overlap” chưa nghĩa “no acoustic samples shared”. Cần biết mức observation mà claim nói.
5. Mask schedules và axis semantics#
Scale phải ghi đơn vị: number patches, frames, ms hoặc fraction grid. 16 time patches với native hop39 ms khác 16 downstream patches/hop10 ms. Frequency patch scale là mel bins, không fixed equal Hz bands. Time/frequency interchange của image-derived masks không vô hại vì speech có time structure và frequency structure khác.
Curriculum đổi geometry/probability theo training, nên target difficulty không stationary. A-JEPA §3 và Algorithm 1 là một recipe curriculum cụ thể; tên A-JEPA khác Audio-JEPA của Tuncay. Không chỉ gộp “curriculum = tăng ratio”: có thể đổi structured-mask probability, scale hoặc separation khi ratio không đổi.
Random higher ratio có thể giảm visible sequence/compute và local shortcuts, nhưng cũng giảm useful context. Same optimizer steps không same compute/mask exposure. Schedules cần read update unit, target coverage và sample weighting.
6. Shortcut có thể đo bằng đối chứng nào?#
High adjacency chỉ cho cơ hội nội suy, chưa chứng minh model dùng local interpolation. Một toy position-only target cho mọi utterance u; predictor trả p_j từ position conditioning, loss0 dù context không chứa utterance information. Cơ chế bài 8 sẽ làm rõ.
Để kiểm một hypothesis về shortcut, cần so contexts shuffled/ablated theo distance, prediction quality ở target interior vs edge, position-only/local baselines, và downstream usefulness under controlled evaluation. Đây là các loại evidence để học cách đọc bài, không một experiment proposal đã chọn hoặc chạy. Mask khó hơn giảm pretraining score mà downstream tốt hơn có thể hợp lý; mask khó hơn mà chỉ tăng ambiguity cũng có thể hại.
Paper SOICT downstream SpecAugment time/frequency bands phục vụ CE classifier; không đo pretraining-mask ablation mới. Ghi chép lịch sử về ~90% neighbor visibility là geometry evidence chưa tái đo ở lớp này; không tự nâng thành causal explanation EER. Chương 06.
Bài tập tăng dần#
- Tính N, |C|, |M| và adjacency của case A/B/D.
- Vì sao D có A=1 giống checkerboard nhưng có thể cần inference khác?
- Với U independent C balanced ±1, MSE optimum/loss là gì? Khi thêm visible V=U thì sao?
- I-JEPA target blocks overlap nhau có đồng nghĩa student thấy target raw content không?
- “Patch removal = zero SpecAugment” sai ở hai bước nào?
- A05 tốt hơn sau đổi masks có đủ để gọi mask forensic-aware không?
Đáp án
- N=32, C=M=16; A=1, B=0,5, D=1 theo 4-neighbor convention.
- A xen kẽ cả time/frequency; D thiếu nguyên frequency bands nhưng vẫn thấy mỗi time ở bands khác. Correlation assumptions theo axis khác nhau.
- Output0, expected error1; với V quan sát, outputV error0. Nếu V noisy, cần posterior conditional khác.
- Không. Context loại target union ở recipe ấy; target–target overlap khác context–target overlap.
- Zero vẫn qua projection/bias/front-end và vẫn có token rows/positions; removal làm sequence ngắn. SpecAugment CE giữ utterance label, SSL masks định nghĩa prediction supervision.
- Không. Validation attack/data, target difficulty, compute và downstream interactions còn cần kiểm; “forensic-aware” cần cue/evidence rõ.
Đào sâu tự chọn#
Tính probability một interior target có ít nhất một visible neighbor dưới independent Bernoulli target ratio r: khi condition node target và neighbors independent. Exact fixed-count sampling without replacement cho hypergeometric expression khác; boundaries có số neighbors khác. Không áp như số chính xác cho Audio-JEPA finite grid/sampler. Script kiểm exact toy geometry, không đo real learned shortcut.